
Identify patterns and trends in Power BI
Introduction
To identify patterns and trends in Power BI, start with the question: Did sales miss a target, did one day behave unusually, or what might happen next quarter? Reference lines, anomaly detection, and forecasting answer those questions in different ways.
This lesson covers the Identify patterns and trends objectives in Visualize and analyze the data (25–30% of the April 20, 2026 PL-300 outline). You will use the Analyze feature, grouping, binning, clustering, AI visuals, reference lines, error bars, forecasting, and outlier detection. You will also use Copilot to summarize a semantic model and see when Python or R is useful for a specialized chart.
Learning objectives
- Add reference lines, trend lines, forecasts, error bars and percentiles from the Analytics pane.
- Group and bin values, and use clustering on a scatter chart.
- Configure key influencers and a decomposition tree and interpret their output.
- Detect anomalies in a line chart and investigate their possible explanations.
- Use Copilot to summarize the semantic model and check the scope of its answers.
- Use Explain the increase and the narrative visuals.
- Decide when a Python or R visual is needed and know its limits.
1. The Analytics pane
The Analytics pane (magnifying-glass icon beside Format) adds analytical overlays to supported visuals (mostly line, bar, column, area and scatter).
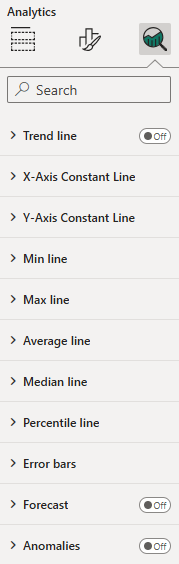
| Feature | Use | Notes |
|---|---|---|
| Constant line | Fixed target or threshold (for example a 1.2 M€ budget) | Static value or a field-based value |
| Min / Max / Average / Median line | Reference for the series | Computed from the visual's data |
| Percentile line | Position of a percentile, such as P90 | Choose the percentile |
| Trend line | Shows the overall direction of a series | Available on supported visuals with time data |
| Forecast | Estimates future values with a confidence band | Single-series line chart with a continuous X-axis; set horizon, confidence interval, and seasonality |
| Error bars | Show a range around each value | Use upper and lower bound fields or percentages where supported; label what the range represents |
| Symmetry shading | Shades the area above or below the diagonal in a scatter | Compare two measures |
| Find anomalies | Marks unusual points on a line chart and explains them | See section 4 |
For a time forecast, use one value on a line chart with a continuous date axis and no legend splitting it into series. Hold back the last N points to test against known results, and choose a seasonal period that matches the data frequency and observed pattern. A 12-point season describes an annual cycle only when each point represents one month. Reference lines apply to the visual; they do not change the model. For a retrospective baseline, see DAX time intelligence and rolling windows.
Error bars in context. If a survey dataset contains a mean satisfaction score and lower and upper confidence bounds for each region, add the bound fields as error bars on a supported chart. Label the confidence level and make sure the bounds use the same grain as the means. A target reference line answers a separate question: how far each region is from the target.
Worked example: forecast and target line
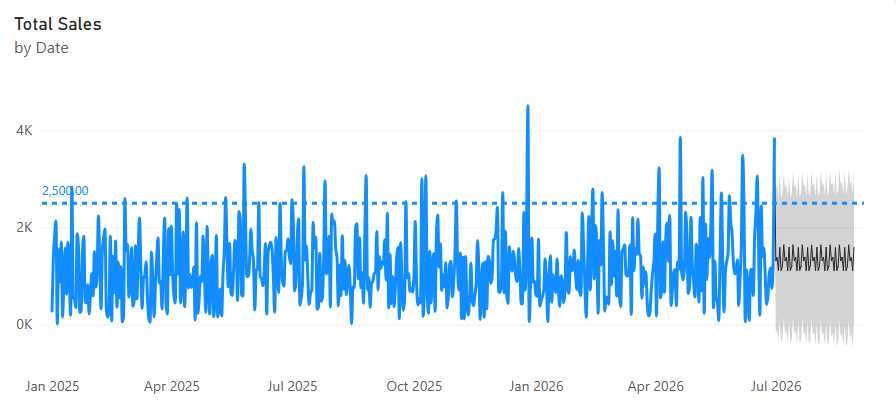
Scenario. A line chart shows 36 months of subscription revenue. The CFO wants the next six months projected with seasonality, to test the forecast against the last three known months, and to see the monthly target of 450 k€ as a horizontal line.
Step 1. Use DimDate[MonthStart] directly as a continuous date on the X-axis, with one point per month and Revenue as the only Y-axis measure.
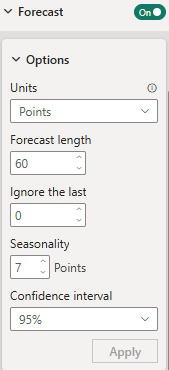
Step 2. Analytics pane → Forecast → On. Set Forecast length to 6 points, Ignore last 3 points, Seasonality 12, Confidence interval 95%.
Step 3. Analytics pane → Constant line → value 450000, title "Target".
Step 4. Compare the estimates for the three held-back months with the actual values. If the error is acceptable for the decision, set Ignore last to 0 so the published six-month forecast starts after the latest actual month.
Why not the alternatives. A calculated column cannot forecast. A measure with moving average smooths past data but does not extrapolate. If Forecast is unavailable, check for a categorical axis or more than one series, and use the raw month-start field instead of the automatic date hierarchy.
2. Grouping, binning, and clustering
Grouping combines categories into custom groups. Right-click a field in a visual → New group, select values and Group. It creates a group column in the model. Select Include Other group if you want a single bucket for unassigned categories. For example, group 40 countries into Sales Territories. Better for few manual groups; for large mappings use a lookup table.
Binning divides numeric or date values into equal-sized bins: right-click a numeric field → New group → Bin with a bin size or a bin count. Examples: age in 10-year bins, order value in 50-€ bins, date in months. Binning plus a count visual builds a histogram. Bins work on numeric or time columns, including calculated columns. Measures cannot be binned directly.
Clustering finds groups of similar points. In Power BI Desktop, build a scatter chart with numeric X and Y values and one point per entity. Use More options → Automatically find clusters when available. Choose the number of clusters or let Power BI choose it. The generated group field can be reused in a legend or slicer. Inspect whether the groups are stable and meaningful before using them in a decision.
Differences: grouping and binning organize data you already have; clustering discovers segments from numeric behaviour.
3. AI visuals: key influencers, decomposition tree, Q&A, smart narrative
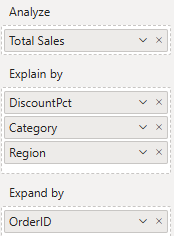
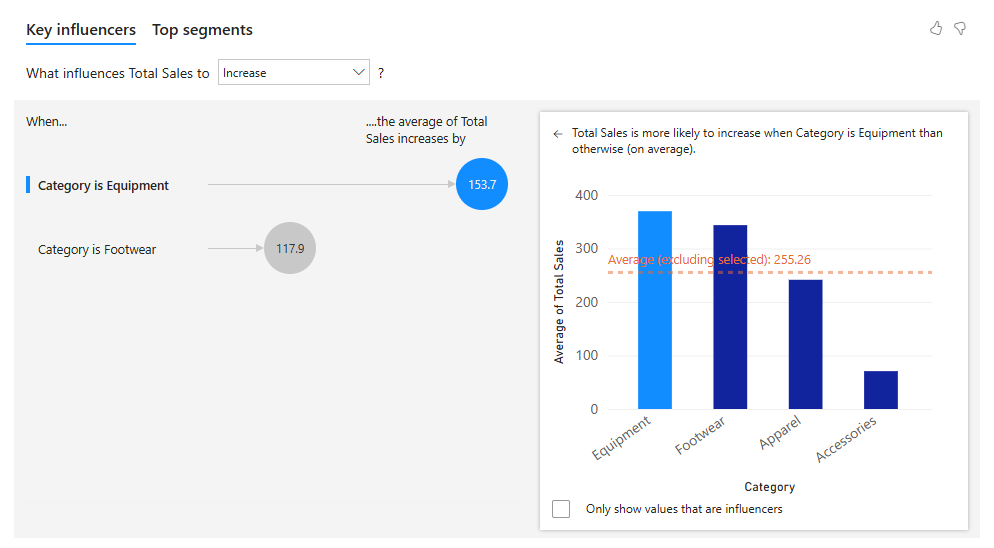
Key influencers. Answers "what drives this metric to be high/low or this category to occur?". Fields:
- Analyze: the metric or category to explain (for instance Churned = Yes, or Rating).
- Explain by: candidate factors, which can be categorical or numeric.
- Expand by: the unit of analysis for aggregated measures (such as Customer ID).
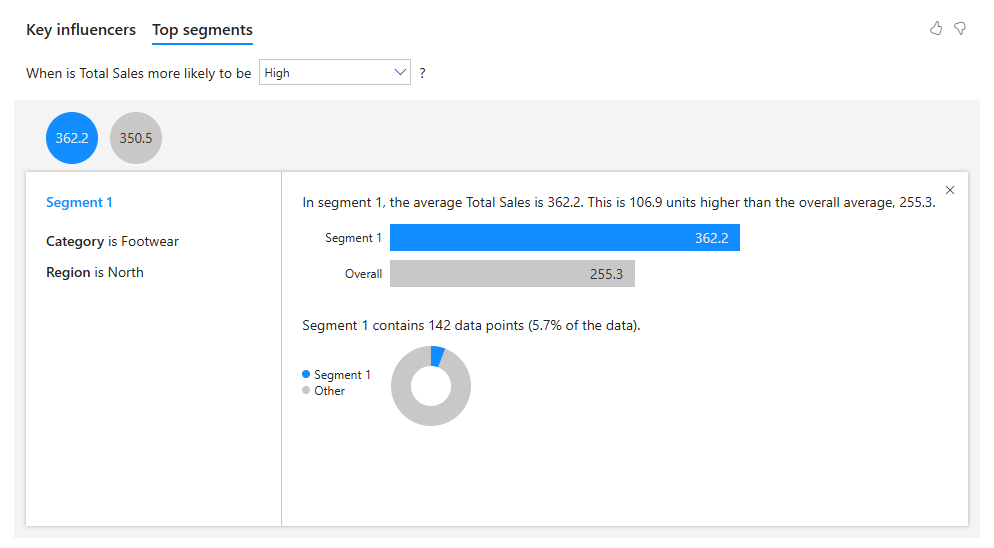
Output: Key influencers tab ranks factors ("when Contract = Month-to-month, the likelihood of churn is 2.3x higher"). The Top segments tab shows combinations of factors with the highest rate. For a numeric target, it reports how the average changes (for example, "when tenure is under 12 months, the average rating decreases by 0.8"). Limits: needs enough rows; when you analyze a measure or a summarized column, the analysis is continuous and runs at the level of the Explain by fields unless you set Expand by (for example an order or customer ID); categorical analysis is unavailable when implicit measures are discouraged. The visual does not support DirectQuery or live connections to Azure Analysis Services or SQL Server Analysis Services. Treat the results as associations: validate the population and possible confounders before acting.
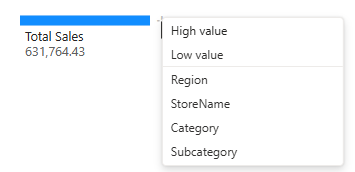
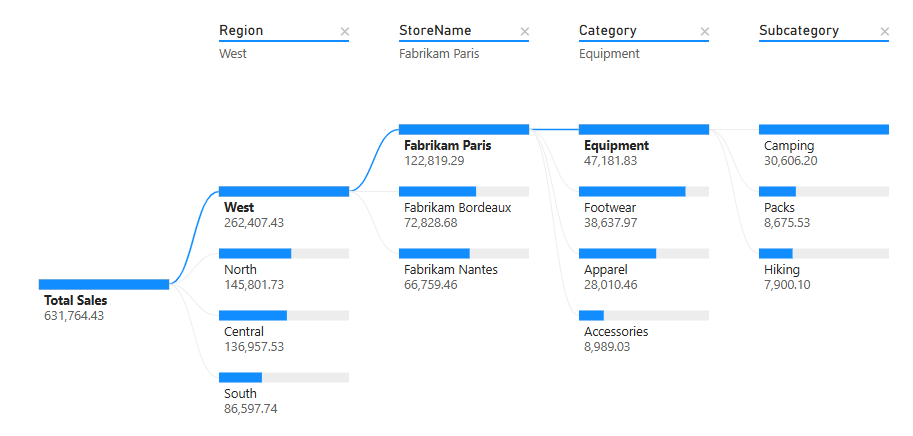
Decomposition tree. Interactive visual that breaks a measure down across dimensions in any order. Fields: Analyze (a measure) and Explain by (dimensions). Readers choose each next dimension, or use High value / Low value (AI splits) to choose a candidate split for the current branch. Absolute mode looks for a high or low value; relative mode looks for a value that stands out within the candidate dimension. Use the result to guide investigation, such as breaking revenue down by region, category, and channel.
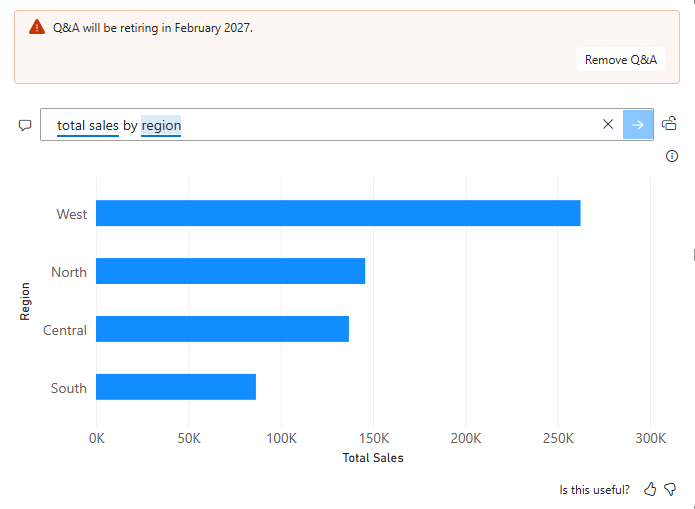
Q&A visual. Readers type questions; Power BI builds a visual. It depends on field names and synonyms in the model (Q&A setup, suggested questions). Microsoft has announced that Q&A will be retired in February 2027 and recommends a transition to Copilot where its requirements are met.
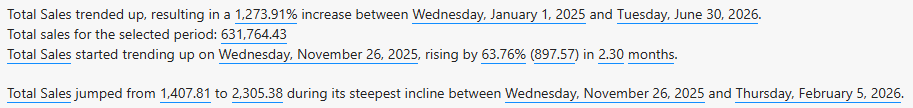
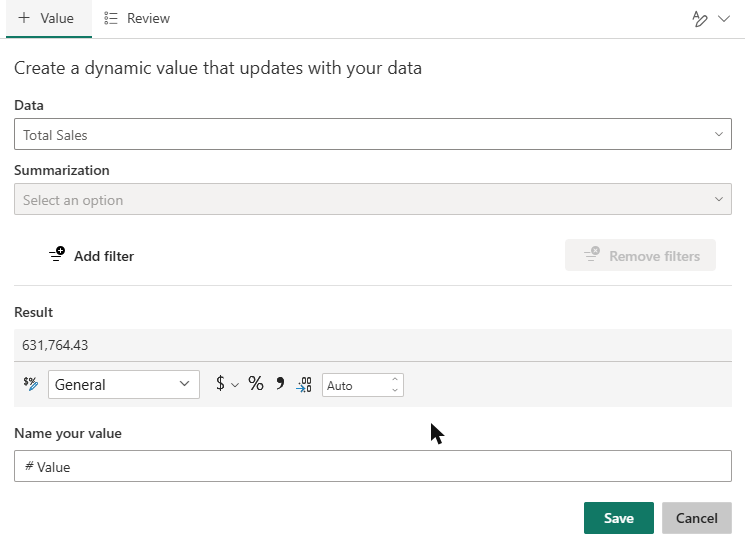
Smart narrative. A visual that writes dynamic text summaries of visuals on the page or report (key takeaways, trends, max/min). The text updates with filters and can be edited and customized with dynamic values from fields or measures. The Copilot narrative summarizes selected report content. To explore the underlying model instead, open the Copilot pane and ask it to summarize the model. If you then ask which region had the highest churn rate last quarter, confirm that the answer uses the intended churn measure, date field, and filters before sharing it. These features require Copilot access.
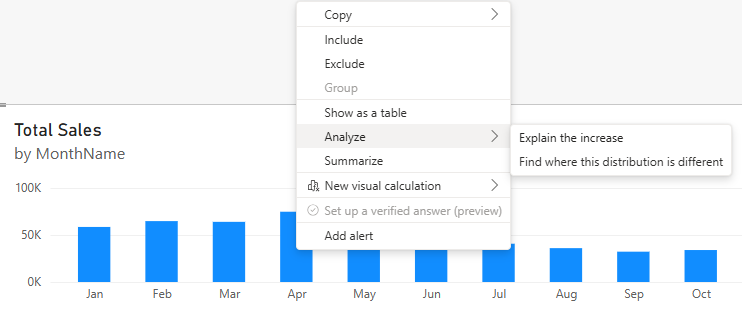
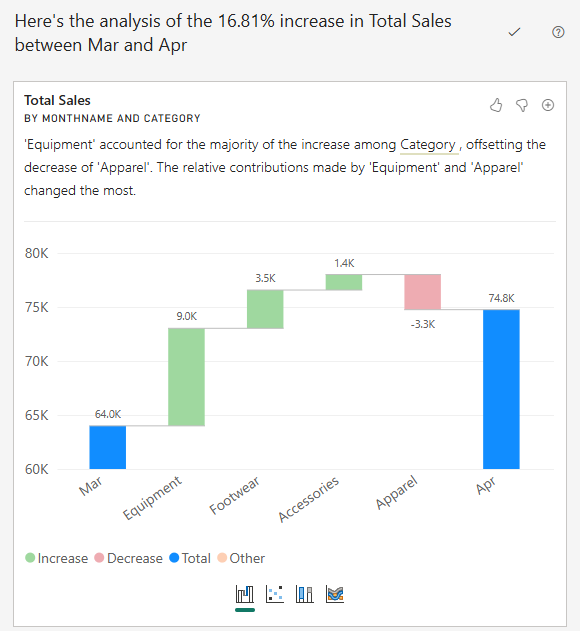
Explain the increase/decrease (Analyze). Right-click a data point on a line or column chart → Analyze → Explain the increase (or decrease) when a point rises or falls compared with the previous one. Power BI tests dimensions in the model and shows visuals (waterfall, scatter, column) listing the factors with the largest contribution. Availability depends on the visual, measure, filters, and source. It explains a change from the previous point, so the visual must be ordered to match the comparison you want. Use it for a quick explanation on a spike without building a decomposition manually.
Worked example: why does churn happen?
Scenario. A telecom table Customers has CustomerID, Contract, Tenure, InternetService, MonthlyCharge, Region, and Churned (Yes/No). The retention team asks which factors are associated with churn and which customer segments have the highest churn rate.
Step 1. Add a Key influencers visual. Drag Churned to Analyze, choose "What influences Churned to be Yes?".
Step 2. Drag Contract, Tenure, InternetService, MonthlyCharge to Explain by. Leave Expand by empty because each row is a customer.
Step 3. Read the Key influencers tab: "Contract is Month-to-month → churn 3.1x more likely". Open Top segments to see "month-to-month, fibre, tenure under 12" with 62% churn versus 27% average.
Step 4. Add a decomposition tree with a churn-rate measure and split it by Contract, then Region. Compare both rates and customer counts before treating a small segment as a priority.
Why the alternatives are worse. A scatter chart would need manual hypotheses. Clustering groups customers by numeric similarity but does not explain a target. A trend line summarizes direction over time and does not rank the factors associated with churn.
4. Anomaly detection and statistical visuals
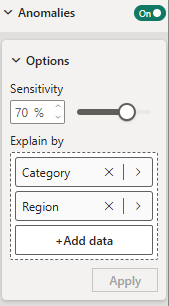
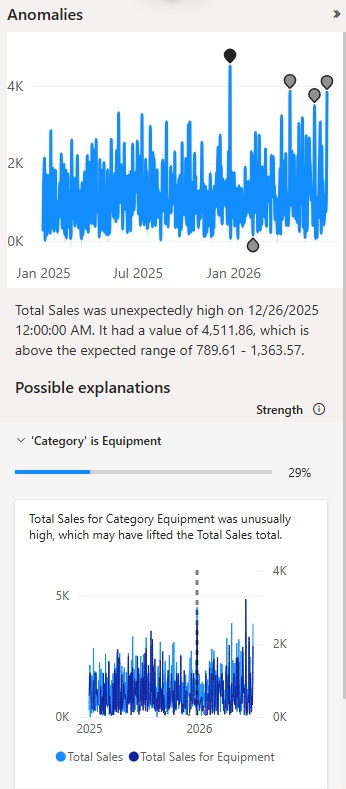
Anomaly detection works on a line chart with a date axis. In the Analytics pane → Find anomalies, set Sensitivity (higher shows more points). Power BI marks anomalies with a symbol and, when a point is selected, shows possible explanations (fields in the model that contributed). You can add expected range shading. Use at least four time-series points, with one value and no legend or secondary value. Forecasts and several statistical reference lines cannot be combined with anomaly detection on the same visual.
Python and R visuals. Enable the scripting runtime in Desktop options. You drag fields into the visual's values; Power BI passes them as a data frame named dataset and the script draws an image with matplotlib, seaborn, ggplot2, etc. Characteristics:
- Runs in Desktop with a local Python/R install; in the service they run in a sandbox with a set of supported packages.
- Output is a static image: no cross-filtering from clicking the image, and tooltips are not interactive.
- Python and R visuals use up to 150,000 rows for plotting. For a Python visual, include an entity key when identical combinations of plotted values must remain separate; Power BI groups the inputs. Check service-specific package and execution limits before publishing.
- Use when no built-in visual provides the analysis (for example a violin plot, a correlation matrix) and the audience accepts a static image.
# dataset has columns: Age, MonthlyCharge
import seaborn as sns, matplotlib.pyplot as plt
sns.regplot(data=dataset, x="Age", y="MonthlyCharge")
plt.show()
Alternatives before choosing a script visual: a custom visual from AppSource (e.g. box and whisker) is interactive and needs no runtime.
Use Show as a table to verify the underlying numbers. If an analysis makes the page slow, see diagnosing report and model performance for how to separate visual rendering from query time.
5. Choosing the feature: decision table
| Question | Feature |
|---|---|
| What will happen next quarter? | Forecast (Analytics pane) |
| Is this point unusual and why? | Anomaly detection with explanation |
| Why did this month rise compared with last month? | Explain the increase |
| What drives churn or a rating? | Key influencers |
| How is the total made up across several dimensions, in the order I choose? | Decomposition tree |
| Which customers behave alike? | Clustering on a scatter chart |
| Show the distribution of order values | Binning + column chart |
| Merge 40 countries into 5 territories | Grouping |
| Compare each point with a target or average | Constant, average or percentile line |
| Write the takeaways in words | Smart narrative or Copilot narrative |
| Statistical plot not available | Python or R visual (static) or custom visual |
Worked example: pick the tool, justify, and discard the others
Scenario. A grocery chain sees online orders spike on 14 March. Analysts must (1) find out whether it is a true anomaly, (2) learn what drove it, and (3) predict next March's volume.
Step 1. On a line chart of daily orders, turn on Find anomalies. Select the 14 March marker to read the explanations (for example promotion SPRING25 and region North).
Step 2. To drill further, right-click the point and use Explain the increase, or build a decomposition tree from order count by channel, region, and promotion.
Step 3. Use a separate chart of monthly orders to forecast next March. If the history supports an annual pattern, test a 12-point season against held-back months and compare the error with a simple baseline.
Why others are worse. Key influencers needs a target field to classify and does not detect time anomalies. Clustering groups points, not dates. A Python visual might do it but is static and slower.
6. Pitfalls and exam tips
- Forecast unavailable: check for a continuous X-axis and a single series.
- Anomaly detection and forecast cannot be used on the same visual.
- Key influencers shows correlation, not causation; when Analyze holds a measure, set Expand by to the right unit (such as an ID).
- Decomposition tree is for exploration with reader control; key influencers is for statistical ranking of drivers.
- Clustering needs a scatter chart (two numeric values and a detail field).
- Binning needs a numeric or date field; grouping works on categories.
- Python/R visuals are static images: no cross-filtering from the image, and the runtime must be installed in Desktop.
- Q&A retirement: Microsoft plans to retire it in February 2027. Know the difference between Copilot questions about a semantic model and specialist visuals such as key influencers.
- Exam tip: map verbs to features: predict → forecast; unusual → anomaly; why/what drives → key influencers; break down → decomposition tree; similar groups → clustering; summarize in words → narrative.
7. Mini case study
Situation. A subscription company with 400 000 customers asks the analyst for: (a) the main factors behind cancellations; (b) six-month forecast of monthly recurring revenue with a visible target of 5 M€; (c) a flag on days where sign-ups jump unexpectedly; (d) customer segments by monthly spend and tenure for marketing; (e) a histogram of customer lifetime value in 100-€ steps; (f) an executive page with a text summary that updates with filters.
Question. Which features answer each request?
Solution, commented.
- (a) Key influencers with
Cancelledin Analyze and plan, tenure, country and support tickets in Explain by. - (b) Forecast on a line chart with one point per month and a constant line at 5,000,000. Test a 12-point season if recurring annual patterns are visible.
- (c) Find anomalies on a separate line chart of daily sign-ups, because it cannot coexist with a forecast on the same visual.
- (d) Clustering on a scatter chart with tenure on X and spend on Y, using one point per customer in a representative sample within the scatter chart limit. Validate the groups on a separate sample before using them for marketing.
- (e) Binning CLV with bin size 100, then a column chart of the customer count.
- (f) Smart narrative (or Copilot narrative if licensed) on the summary page.
Why not the alternatives. A decomposition tree helps exploration for (a), but the request is to rank the factors. A calculated column for the histogram bins would work but the built-in bin is faster to maintain. A Python script for clustering would be static.
Key terms
- Analytics pane: overlay tools (lines, trend, forecast, anomalies) on visuals.
- Forecast: time-series prediction with a confidence band.
- Binning: grouping numeric or date values into equal intervals.
- Clustering: automatic grouping of similar points in a scatter chart.
- Key influencers: AI visual ranking factors associated with a metric or outcome.
- Decomposition tree: visual breaking down a measure by dimensions chosen by the reader.
- Anomaly detection: automatic marking of unusual points on a time-series line.
- Smart narrative: auto-generated, editable text summary.
- Seasonality: the number of points in a repeating cycle.
Summary checklist
- I can add constant, average, percentile and trend lines, and configure a forecast.
- I know why a forecast may be unavailable.
- I can group, bin and cluster data.
- I can set up key influencers and a decomposition tree and interpret them.
- I can enable anomaly detection and know its limits.
- I know what Python and R visuals can and cannot do.
- I can map a business question to the correct analysis feature.
Official sources
- Study guide for Exam PL-300: https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/pl-300 (opens in a new tab)
- Analytics pane in Power BI Desktop: https://learn.microsoft.com/en-us/power-bi/transform-model/desktop-analytics-pane (opens in a new tab)
- Key influencers visualizations: https://learn.microsoft.com/en-us/power-bi/visuals/power-bi-visualization-influencers (opens in a new tab)
- Anomaly detection: https://learn.microsoft.com/en-us/power-bi/visuals/power-bi-visualization-anomaly-detection (opens in a new tab)
- Decomposition tree: https://learn.microsoft.com/en-us/power-bi/visuals/power-bi-visualization-decomposition-tree (opens in a new tab)
- Use Copilot with Power BI reports and semantic models: https://learn.microsoft.com/en-us/power-bi/create-reports/copilot-reports-overview (opens in a new tab)
- Scatter charts in Power BI: https://learn.microsoft.com/en-us/power-bi/visuals/power-bi-visualization-scatter (opens in a new tab)
- Q&A in Power BI: https://learn.microsoft.com/en-us/power-bi/visuals/power-bi-visualization-q-and-a (opens in a new tab)