
PL-300: Optimize Power BI Model Performance
Find what makes a Power BI report slow
A slow visual can spend time waiting for its query, drawing its results, or waiting for other work. Power BI model performance improves when you measure the bottleneck and verify that the faster version still returns the intended numbers.
This lesson covers Optimize model performance in the PL-300 Model the data domain (25–30% of the exam, skills measured from April 20, 2026). You will reduce unnecessary data, diagnose slow queries and visuals with Performance Analyzer and DAX query view, and choose an appropriate fact-table grain.
Learning objectives
- Explain how the VertiPaq engine compresses columns and why cardinality drives model size.
- Remove unnecessary rows, columns and tables, and avoid auto date/time overhead.
- Choose better data types and split high-cardinality columns.
- Use Performance Analyzer to separate DAX query time, visual display time and other time.
- Run and edit a visual's DAX query in DAX query view and test a measure rewrite.
- Reduce granularity by summarizing fact tables, and know when to use aggregations or mixed storage modes.
1. Why models are slow: how Import mode stores data
In Import mode, Power BI stores each table in the in-memory VertiPaq engine, column by column. Each column is compressed using dictionaries (a list of the distinct values), run-length encoding and value encoding. Three consequences matter for the exam:
- Both row count and column content matter. Low-cardinality columns often compress well. A unique GUID or a free-text comment can take much more space, depending on data type, value lengths, and encoding. Measure which columns are largest.
- Cardinality (the number of distinct values in a column) is one driver of storage and can affect grouping and filtering costs. Query cost also depends on the model, measure, and visual.
- Calculated columns are stored in the model and increase its size, whereas measure results are computed on demand and do not add a stored value to every source row.
Slow reports have three typical causes: a model that is too big (long refresh, high memory), DAX measures that are expensive, and visuals that issue too many or too heavy queries.
| Symptom | Likely cause | First action |
|---|---|---|
| File size very large, refresh slow | Unneeded columns, high-cardinality columns, too many rows | Remove columns/rows, reduce granularity |
| One visual slow, others fast | Expensive measure or visual with thousands of points | Performance Analyzer, DAX query view |
| Every visual slow | Shared measure, model, source, capacity, or page-wide workload | Compare timings across pages and isolate the shared cause |
| Report slow on DirectQuery | Source database slow or poorly indexed | Optimize source, aggregations, Import for dimensions |
2. Remove unnecessary rows and columns
The cheapest data is the data you never load.
Remove columns that no visual, measure, relationship, row-level security rule or filter uses. In Power Query, use Choose columns or Remove columns, preferably early in the query so that query folding pushes the projection to the source. Typical removals: technical keys not used in relationships, audit columns (CreatedBy, ModifiedAt), description fields, duplicated text versions of codes.
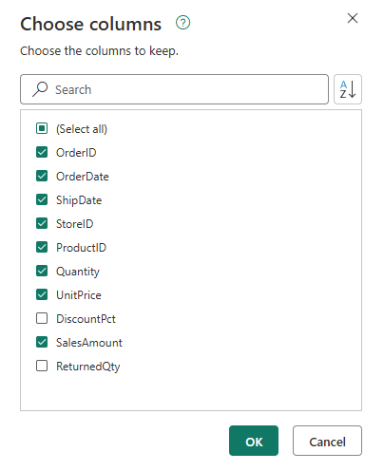
Remove rows you do not need: cancelled test orders, years outside the business need, other regions. Filter in Power Query (Table.SelectRows), ideally with a step that folds to the source, or use a WHERE clause in a native query. Another way to limit data is to apply incremental refresh with RangeStart and RangeEnd parameters, which refreshes the configured recent partitions after initial load. The archive policy controls how much history is retained. A rolling refresh window alone does not remove all older data.
Disable load for staging queries (right-click → uncheck Enable load) when only the downstream tables belong in the model. See query folding and loading data with Power Query.
Auto date/time. Auto date/time creates hidden tables for eligible Import date columns. A shared date dimension can reduce duplication. Check visuals that use automatic hierarchies before switching it off.
Data types. Use whole numbers for integral quantities and preserve text for codes whose characters matter. Choose fixed decimal for a compatible monetary scale. Measure the size impact rather than assuming one numeric type is always smaller. Reduce precision only where accuracy and reconciliation requirements allow it.
Hide, don't delete? Hiding a column in Report view does not reduce its size, because the column is still stored. Only removing it from the model does.
Worked example: shrinking a 900 MB model
Scenario. The sales model is 900 MB. FactSales has 40 million rows and these columns: OrderID, OrderTimestamp (date and time to the second), ProductKey, CustomerKey, Quantity, Amount (decimal with 6 digits), Comment (free text), CreatedBy, RowGuid. Reports use only monthly and daily sales, by product and customer.
Step 1 – find the heaviest columns. An external model size tool such as DAX Studio’s VertiPaq metrics can show actual column sizes. RowGuid, Comment, and OrderTimestamp are candidates to inspect. Without these tools, reason about distinct values: a GUID is unique per row; the timestamp has up to 86,400 values per day.
Step 2 – remove what is unused. Delete RowGuid, Comment, CreatedBy in Power Query. They are used by no visual, measure or relationship.
Step 3 – split the timestamp. Reports need only the date, so create OrderDate (type Date) and drop the time part, relating OrderDate to the date table. If the time of day is needed, keep it as a separate low-cardinality column (hour of day), not as a seconds-level timestamp.
Step 4 – fix types. Check required monetary precision. Rounding each line can change totals. Preserve the six-decimal source amounts unless finance approves a different scale and reconciliation passes.
Step 5 – reduce granularity if allowed. If no report needs individual order lines, group by date, product and customer, which could cut 40 million rows to a few million (see section 5).
Why other choices are worse. Hiding the columns leaves them stored. DirectQuery can reduce imported data, but query latency then depends on the source and workload. Compare it only if storage or freshness requirements justify it.
3. Performance Analyzer
Performance Analyzer is a pane in Power BI Desktop (Optimize ribbon → Performance analyzer; also available in the Power BI service in edit mode). It records the time taken to update each visual after a user action.
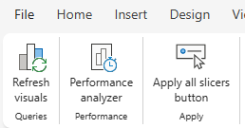
How to use it:
- Open the report page, select Start recording.
- Select Refresh visuals (or interact: change a slicer, open a page).
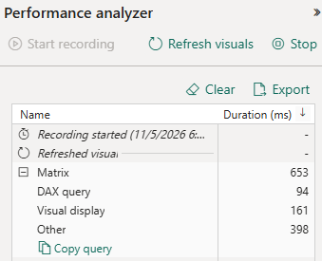
- Read the results: for each visual, the time is split into:
- DAX query: time for the semantic model to return data. Long values prompt investigation of the measures, relationships, and source work used by that query.
- Visual display: time to render the visual, including work such as retrieving web images or geocoding. High values can come from many data points or other display work.
- Direct query can report external query time for DirectQuery. Other can include preparing a query, waiting, and background processing. Treat these as clues, not a server execution trace.
- Use Copy query to copy the DAX query for a visual, or Run in DAX query view to open it directly in DAX query view.
- Use Export to save the results as JSON.
Typical conclusions:
| Observation | Meaning | Action |
|---|---|---|
| High DAX query, low display | Measure or model is slow | Test the measure in DAX query view, review relationships |
| High display, low DAX | Visual draws too many marks | Reduce points, change visual type, use filters or top N |
| Many visuals on a page, all slow | Page too heavy; queries compete | Fewer visuals, bookmarks or drillthrough pages, Apply all slicers |
| First load slow, later fast | Possible cache effects or startup work | Compare first-run and repeat-run timings separately |
Tip: record several comparable runs using the same filters, page, data, and environment. Compare warm runs separately from cold runs. Reopening the report does not guarantee that every cache layer is empty.
Other report-side practices: limit the number of visuals per page; avoid visuals with thousands of categories on an axis; use "Apply" buttons for slicers (Query reduction settings) so that the report does not query on every selection; prefer slicers on low-cardinality columns; and use drillthrough instead of a huge detailed table on the main page.
4. DAX query view
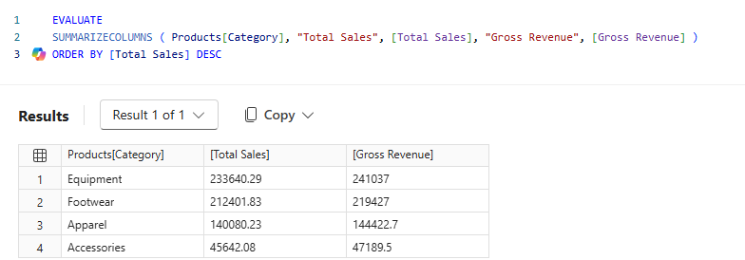
DAX query view (available in Power BI Desktop and in supported service model-editing scenarios) lets you write and run DAX queries that start with EVALUATE against the semantic model, without leaving Desktop. You can:
- run DAX queries against the model, including queries copied from Performance Analyzer;
- use Quick queries (right-click a table, column or measure) to generate queries such as showing the top 100 rows of a table, or a column's statistics;
- define measures in the query with
DEFINE MEASURE, test them, and then update the model with changes to push them into the semantic model; - inspect results and compare timings under equivalent conditions. Use writing and testing DAX measures to check which filters the original measure is intended to preserve.

DEFINE
    MEASURE FactSales[Sales Test] =
        SUMX ( FactSales, FactSales[Quantity] * FactSales[UnitPrice] )
EVALUATE
SUMMARIZECOLUMNS (
    DimDate[Year],
    DimProduct[Category],
    "Sales", [Sales Test]
)
ORDER BY DimDate[Year], DimProduct[Category]
Typical workflow for a slow visual: copy its query from Performance Analyzer into DAX query view, run it and note the time, rewrite the measure (for example, use a Boolean filter when it preserves the intended result, or store a repeated expression in a variable in the same evaluation context), run again and compare results as well as timings. Check several slicer states and totals before updating the model. DAX query view also displays a result grid limited to a maximum number of values, so it is for diagnosis, not for exporting data.
Measure-level optimizations the exam may mention:
| Slow pattern | Better pattern | Why |
|---|---|---|
| Whole-table filter for a same-column condition | A Boolean filter with KEEPFILTERS if existing filters should intersect |
Can reduce work. A filter over ALL ( Sales ) may have different semantics. |
| Repeating the same expression several times | Variable (VAR) |
Evaluated once |
/ with possible zero |
DIVIDE |
Avoids errors; readable |
| Calculated column that could be a measure | Measure | Not stored, computed only when needed |
| Bidirectional filters everywhere | Single direction, bridge via CROSSFILTER in a measure when needed |
Fewer filter propagations |
| Many-to-many relationships on large tables | A verified bridge and clear filter paths | Resolves the intended grain and relationships before tuning |
5. Reduce granularity
Granularity (grain) is the level of detail of a table: one row per order line, per order, per day. If reports never need the detail, store a coarser grain.
Ways to reduce it:
- Group by in Power Query (or SQL view): summarize the fact to day × product × customer with sums of amount and quantity. Distinct order counts, ratios, and medians generally cannot be reconstructed by summing results from groups. Keep the detail or the correct supporting data when reports need them.
- Reduce precision when allowed: use a date or hour instead of an unused timestamp, or add meaningful ranges for slicing. Verify that precision changes preserve reporting requirements.
- Split a high-cardinality column into two lower-cardinality columns (date and time; a long code into prefix and suffix).
- Aggregations (user-defined): keep a detailed table in DirectQuery and a small summarized table in Import; configure the aggregation table with Manage aggregations so that queries at a high level hit the summary and only drill-downs go to the source. Related approach: composite models with a mix of storage modes (Dual for dimensions).
- Incremental refresh to limit what is refreshed; hybrid tables can add a real-time DirectQuery partition beyond the imported range when the configuration supports it.
Coarser grain usually lowers the amount of imported data. It also limits which metrics and drill-downs can be reconstructed. Choose the grain based on the lowest level the business questions need.
Comparison of options for a very large fact table
| Option | Model size | Query speed | Detail kept | Typical use |
|---|---|---|---|---|
| Import, full detail | Large | Fast | Full | Moderate volume |
| Import, summarized grain | Small | Fastest | Reduced | Reports do not need line detail |
| DirectQuery | Tiny | Depends on the source | Full | Real time or huge volume |
| Composite with aggregations | Medium | Fast for summary, slower on drill | Full (in source) | Large volume with summary dashboards |
6. Pitfalls and exam tips
- Hiding is not removing: hidden columns still use memory.
- Calculated columns increase model size: prefer measures, or create the column upstream in Power Query or the source.
- Performance Analyzer shows where time goes; DAX query view lets you test a fix. The exam may ask which tool to use first: Performance Analyzer.
- High display time warrants checking the number of data points, custom visuals, images, and geocoding before rewriting DAX.
- Disable auto date/time and use one shared date table.
- Cardinality is about distinct values, not rows. Removing a unique ID column often helps more than removing thousands of rows.
- Exam tip: "reduce model size without losing needed reports" usually means removing unused columns/rows, correcting data types and summarizing; "slow measure" usually means rewriting DAX and testing it in DAX query view.
7. Mini case study: speed up a daily energy report
Situation. An Import model has 400 million minute readings. The daily regional report needs positive consumption and a separate count of negative readings used for quality checks. Its slowest visual takes 15.5 seconds for the query and 1.2 seconds to display. The current measure scans the whole readings table and clears its filters, which can also change the region totals.
- Record timings and compare the current results against approved regional totals. Determine which filters the consumption measure should respect.
- Remove unused payload and firmware columns after checking dependencies. Keep the timestamp in the source if the business still needs to investigate individual readings.
- Aggregate at meter and day grain, assuming the meter-to-region mapping is valid for each day. Compute positive kWh and negative-reading count from the raw readings before grouping. For readings of 6 and −4 kWh on one day, positive consumption is 6, while net consumption is 2. Filtering daily net amounts would change the metric.
- Sum the positive-consumption column in the summary model and use the region and date dimensions to filter it. Reconcile totals and quality counts across several periods. Keep a separate detail path if investigators still need minute readings.
- Re-record the same page and filters. Compare several runs and confirm that the faster result matches the business definition.
One complete day contains at most 1,440 minute slots per meter. The actual row reduction depends on how many readings are present and whether there can be multiple readings per slot.
Key terms
- VertiPaq: in-memory columnar engine used by Import mode.
- Cardinality: number of distinct values in a column.
- Granularity (grain): level of detail of a table row.
- Performance Analyzer: Desktop and service tool recording DAX query, display and other time per visual.
- DAX query view: Desktop view to write and run DAX queries and test measures.
- Aggregation table: summarized table used to answer high-level queries.
- Composite model: model mixing Import, DirectQuery and Dual tables.
- Incremental refresh: refreshing only new or changed partitions.
- Auto date/time: hidden date tables created per date column.
Summary checklist
- I can explain why cardinality, not row count alone, drives model size.
- I can remove unnecessary rows and columns and disable auto date/time.
- I can pick efficient data types and split timestamps.
- I can read Performance Analyzer's DAX query, visual display and other times.
- I can run, edit and test a visual's query in DAX query view.
- I can reduce granularity with grouping, aggregations or composite models.
- I know hiding a column does not reduce model size.
Official sources
-
Study guide for Exam PL-300: https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/pl-300 (opens in a new tab)
-
Use Performance Analyzer: https://learn.microsoft.com/en-us/power-bi/create-reports/performance-analyzer (opens in a new tab)
-
DAX query view: https://learn.microsoft.com/en-us/power-bi/transform-model/dax-query-view (opens in a new tab)
-
Optimize a model for performance (training): https://learn.microsoft.com/en-us/training/modules/use-tools-optimize-power-bi-performance/ (opens in a new tab)
-
Troubleshoot report performance: https://learn.microsoft.com/en-us/power-bi/guidance/report-performance-troubleshoot (opens in a new tab)
-
Microsoft Learn, Import model data reduction: https://learn.microsoft.com/en-us/power-bi/guidance/import-modeling-data-reduction (opens in a new tab)
-
Microsoft Learn, aggregations and incremental refresh: https://learn.microsoft.com/en-us/power-bi/transform-model/aggregations-advanced (opens in a new tab) and https://learn.microsoft.com/en-us/power-bi/connect-data/incremental-refresh-overview (opens in a new tab)
-
DAX Studio, model metrics: https://daxstudio.org/docs/features/model-metrics/ (opens in a new tab)