
PL-300: Transform and Load Data with Power Query
Turn source data into tables you can model
A budget workbook has a column for each month, while the report needs one row per month and business unit. Transforming and loading data with Power Query means choosing the right row grain, reshaping the data, and deciding which queries belong in the semantic model.
This lesson covers Transform and load the data in the PL-300 Prepare the data domain (25–30% of the exam, skills measured from April 20, 2026). It builds on profiling and cleaning data in Power Query and covers types, grouping, reshaping, keys, joins, and query load settings.
Learning objectives
- Set and verify column data types, including types that affect later aggregation and relationships.
- Create and transform columns (split, extract, conditional, custom, index, duplicate, format).
- Group and aggregate rows, and pivot, unpivot and transpose tables.
- Expand semi-structured data (JSON, XML, nested records and lists).
- Identify fact and dimension tables and build them from a flat source.
- Choose between reference and duplicate queries, and between merge and append.
- Choose keys that support relationships and configure query load (enable load, include in refresh).
1. Column data types
Every column in Power Query has a data type, and the type drives sorting, aggregation, formatting and relationship matching. The main types are Whole Number, Decimal Number, Fixed Decimal Number (currency, four decimals, stored as an integer scaled by 10,000), Percentage, Date/Time, Date, Time, Date/Time/Timezone, Duration, Text, True/False and Binary.
Key points:
- For unstructured sources such as CSV and text, automatic header and type detection can inspect the first 200 rows when enabled. Review the resulting steps; later rows may contain a different format. Structured connectors can supply source type information.
- Fixed Decimal Number stores exact values at a scale of four decimal places within its range. Use it for amounts when that scale is sufficient. Decimal Number uses binary floating point and can introduce small precision differences. Neither type replaces a business rounding rule.
- Identifiers such as
ProductCode = "00123"must stay Text. Converting to Whole Number removes leading zeros and breaks matches against other systems. - Numbers that are really categories (a
StatusCodeof 1, 2, 3) should be Text so they are never summed. - Locale matters. Use Change Type → Using Locale when the source uses a different decimal separator or date order (covered in the previous lesson).
- A relationship requires both columns to have the same data type. Align both types and values explicitly before building a relationship, and preserve leading zeros where they are part of the key.
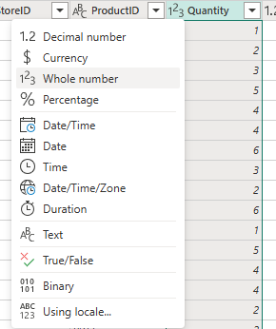
Example. Fabrikam Retail loads Sales.csv. OrderDate arrives as Text "2025-03-14". The analyst changes it to Date, otherwise the Date table relationship (which uses a Date column) cannot be created and time intelligence will fail. ProductCode stays Text because it contains values such as "007-A".
2. Creating and transforming columns
Transform versus Add Column
The Transform tab changes the selected column in place; the Add Column tab creates a new column and keeps the original. Choose Add Column when you may need the raw value again, and Transform when the original has no further use.
Common column operations
| Need | Where | Result |
|---|---|---|
Split "Smith, John" into two columns |
Transform or Home → Split Column → By Delimiter | Two text columns |
| Take the first 3 characters of a code | Transform → Extract → First Characters | Region prefix |
| Combine first name and last name | Add Column → Custom Column or select columns → Merge Columns | FullName |
| Label rows by rule | Add Column → Conditional Column | Size = if Qty > 100 then "Bulk" else "Standard" |
| Number rows | Add Column → Index Column (from 0 or 1) | Row position or a model-local surrogate key if the mapping is rebuilt consistently |
| Copy a column | Add Column → Duplicate Column | Starting point for another transformation |
| Date parts | Transform → Date → Year, Month, Day of Week | Year, Month Name |
| Column from examples | Add Column → Column From Examples | Power Query infers the M formula from sample outputs |

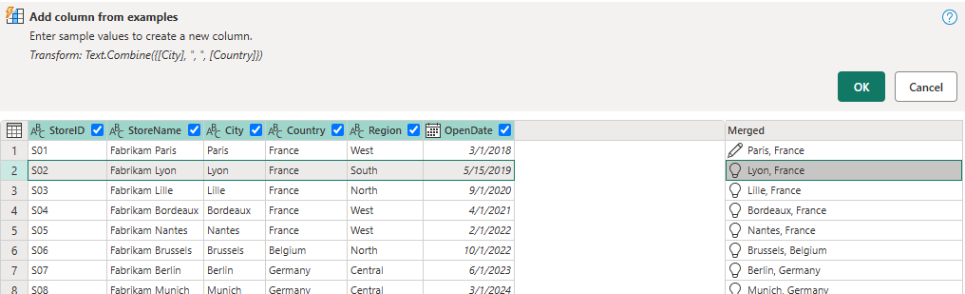
A Custom Column uses M:
= Table.AddColumn(#"Changed Type", "Margin", each [Revenue] - [Cost], type number)Important detail: M is case-sensitive (Text.Upper, not text.upper), and each [Revenue] refers to the field in the current row.
Where should a calculation live?
A frequent exam theme is Power Query column or DAX? Rules of thumb:
- If the value is a property of the row and does not depend on user filters (a margin per line, a cleaned category), computing it in Power Query (or the source) is best. In Import mode it is calculated at refresh and stored; high-cardinality results can increase model size.
- If the value must react to slicers and filters (a ratio of totals, a year-to-date amount), use a DAX measure.
- Prefer a column added in Power Query over a DAX calculated column when the source supports query folding, because folded steps run in the source system.
3. Grouping and aggregating
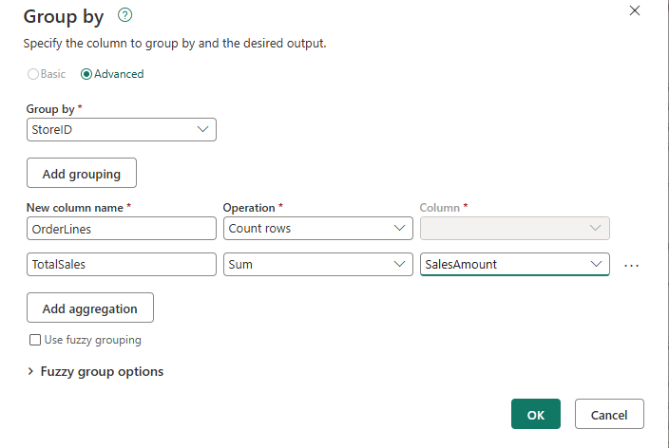
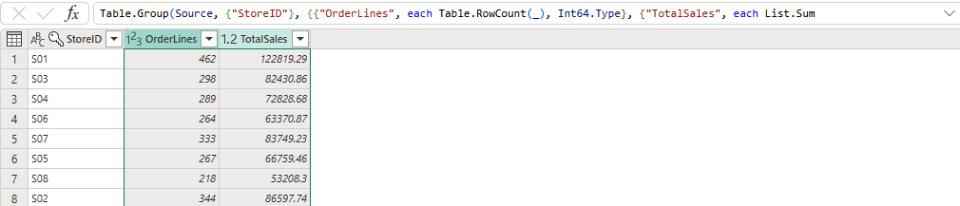
Group By (Home or Transform tab) collapses rows into groups and aggregates them: Sum, Average, Median, Min, Max, Count Rows, Count Distinct Rows and All Rows (returns a nested table for each group).
Example. A logistics company has 40 million scan events but reports only need one row per parcel per day. Grouping by ParcelID and ScanDate with a Count Rows aggregation reduces the table to about 6 million rows. The model is smaller, refreshes faster and every report still works at the daily grain. The trade-off: after grouping, detail below that grain can no longer be analysed, so confirm the required granularity first.
Details to remember:
- The Advanced option allows several group columns and several aggregations.
- Count Distinct Rows counts distinct rows in a group; Count Rows counts all rows. Count Distinct Values is a separate operation Microsoft documents for Power Query Online. In Desktop, an M aggregation can use
List.DistinctandList.Counton the chosen column. Decide whether to exclude nulls. - Grouping early (and on foldable sources) can be pushed to the source as a
GROUP BYquery. - For a null group key, decide whether to retain it, map it to an Unknown member, or investigate it before aggregation.
4. Pivot, unpivot and transpose
Reporting tools prefer tall, narrow tables (one value per row), whereas spreadsheets are often wide (months in columns). Reshaping is a core skill.
| Operation | Starting shape | Result | Typical use |
|---|---|---|---|
| Unpivot Columns | Columns Jan, Feb, Mar with sales |
Two columns: Attribute (month) and Value (sales) |
Convert a wide Excel budget into a fact table |
| Unpivot Other Columns | Select the identifier columns, unpivot everything else | Same, but robust when new month columns appear | Preferred for sources that grow |
| Unpivot Only Selected Columns | Unpivot only the chosen columns | Fixed list of columns | Source with stable columns |
| Pivot Column | Rows with Metric = "Sales", "Cost" |
One column per metric | Turn attributes into columns |
| Transpose | Rows become columns and the reverse | Flipped table | Fixing a sheet turned on its side; then Use First Row as Headers |
Exam tip: if the question mentions that new columns (for example a new month) will be added to the source regularly, choose Unpivot Other Columns, because it unpivots everything except the columns you keep, including future ones. Use Unpivot Only Selected Columns if the list must stay fixed. With Unpivot Other Columns, validate attribute names so new metadata columns are not mistaken for periods.
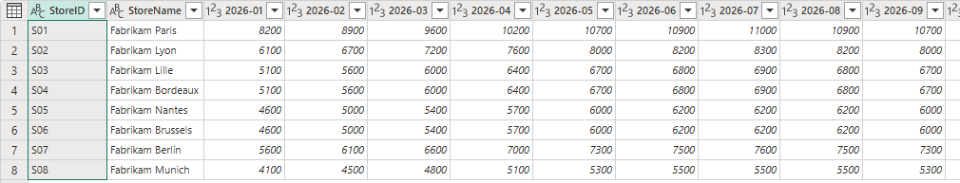
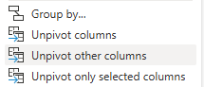
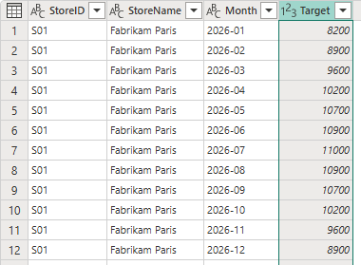
For Pivot Column, you choose the column whose values become headers and the values column, plus an aggregation (Sum, Count, Don't Aggregate). If multiple values land in one pivot cell, the chosen aggregation determines the result. Don’t Aggregate needs at most one value per cell and can error on duplicates.
Worked example 1: unpivoting a budget workbook.
Scenario. Contoso Foods keeps Budget.xlsx with columns Region, Category, Jan, Feb, ..., Dec. A new workbook version each year may add a Q4 Adjustment column. The model needs Region, Category, Month, Amount.
Reasoning.
- Promote the headers, set
RegionandCategoryas Text. - Select
RegionandCategory, then choose Unpivot Other Columns. All remaining columns become two columns,AttributeandValue. - Rename
AttributetoMonth,ValuetoAmount, and setAmountto Fixed Decimal Number. - Validate period labels. Keep
Q4 Adjustmentfor reconciliation and map it to a month only if finance has approved a mapping; otherwise report it separately. - Load the table as a fact table.
Why the other choices are worse. Using Unpivot Only Selected Columns with a fixed list leaves future period columns untouched. Transpose swaps rows and columns but does not produce a tall table with a repeated attribute. Pivot does the opposite of what is needed. Writing twelve separate measures in DAX instead of reshaping creates maintenance work and a poor model.
5. Semi-structured data
Sources such as JSON, XML and some web APIs return records (a row of named fields), lists (an ordered set of values) and nested tables. In the editor you see clickable Record, List or Table cells, and the expand icon at the top right of the column.
Steps to flatten:
- Convert a list to a table when needed (To Table).
- Expand the record column to pick the fields you want. Untick Use original column name as prefix if the names are unique.
- If there is a nested table or list, expand again with Expand to New Rows (a list with three elements becomes three rows) or Extract Values (joins list elements into one text value with a delimiter).
- Set data types on the final columns.
The M functions behind this are Json.Document, Xml.Tables, Table.ExpandRecordColumn and Table.ExpandListColumn. The expansion lists fields explicitly. Normalize optional fields first, for example by constructing records with Record.FieldOrDefault. Check required fields separately. Expanding lists repeats parent values, so do not sum order-level totals across order lines.
Example. An e-commerce API returns orders as JSON; each order has a lines list with product and quantity. Expanding lines to new rows yields one row per order line, which is exactly the grain of a sales fact table. If you used Extract Values instead, you would get one row per order with a text list of products, which is useless for aggregation.
6. Fact and dimension tables
The recommended shape for Power BI is a star schema: central fact tables surrounded by dimension tables.
| Fact table | Dimension table | |
|---|---|---|
| Rows represent | Events or measurements (a sale, a click, a shipment) | Things you filter and group by (a product, customer, date) |
| Typical columns | Keys to dimensions, numeric measures (quantity, amount) | A unique key, descriptive attributes (name, category, city) |
| Size | Many rows | Few rows relative to facts |
| Key property | Foreign keys repeat | The key is unique |
Source systems often deliver a flat, denormalised table, such as one Sales export with OrderID, OrderDate, CustomerID, CustomerName, CustomerCity, ProductCode, ProductName, Category, Quantity, Amount. To get a star schema:
- Create a reference to the flat query for each dimension (see the next section).
- In the customer reference, keep
CustomerIDand its attributes. Verify one row per ID. Resolve conflicting attributes with an authoritative source or a versioning rule. Names and cities do not identify customers reliably. - Repeat for products.
- Keep stable keys in the fact. If you need surrogate keys, apply a consistent mapping and validate that merges do not multiply fact rows.
- Load the three tables, then continue with designing relationships in a Power BI data model to choose cardinality and filter direction.
Benefits: smaller model (descriptive text stored once), faster filtering, simpler DAX, and relationships that behave predictably.
7. Reference versus duplicate queries
Both create a new query from an existing one, but they behave differently.
| Reference | Duplicate | |
|---|---|---|
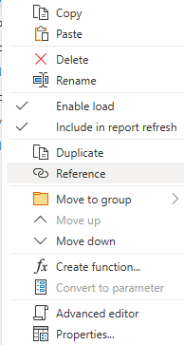
| What it creates | A new query whose first step reads the output of the original | A full independent copy of all steps |
| Source execution | Can run separately for each downstream query | Independent steps can request the same source again |
| If you change the original | The reference inherits the change | The copy does not change |
| Typical use | Build several dimension tables from one cleaned staging query | Start a variant of a query that will diverge |
Reference is the right choice for the staging pattern: one query connects and cleans the file (Sales_Raw, load disabled), and several queries reference it to produce DimCustomer, DimProduct and FactSales. A fix to a data-type step in the staging query then reaches all of them. Use duplicate only when you intend the copies to evolve independently. Reference shares logic. It does not guarantee a single read, and buffering the staging query does not create a shared cache across downstream evaluations. Consider persisted staging if repeated reads are expensive.
8. Merge and append
Append: stack rows
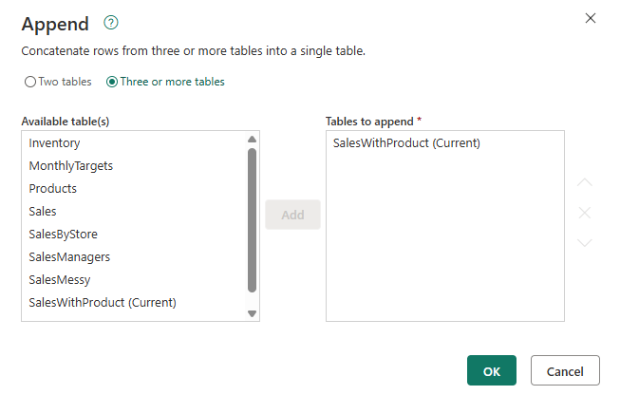
Append Queries (Home → Combine) stacks tables with the same purpose, for example monthly files Sales_2025_01 ... Sales_2025_12, or sales from two regional systems. Columns are matched by name; columns present in only one table are kept and filled with null in the other. Choose Append Queries as New to keep the originals. When files live in a folder, Combine Files applies the same transformation to each file and appends automatically, which is preferable to appending dozens of queries by hand.
Merge: join columns
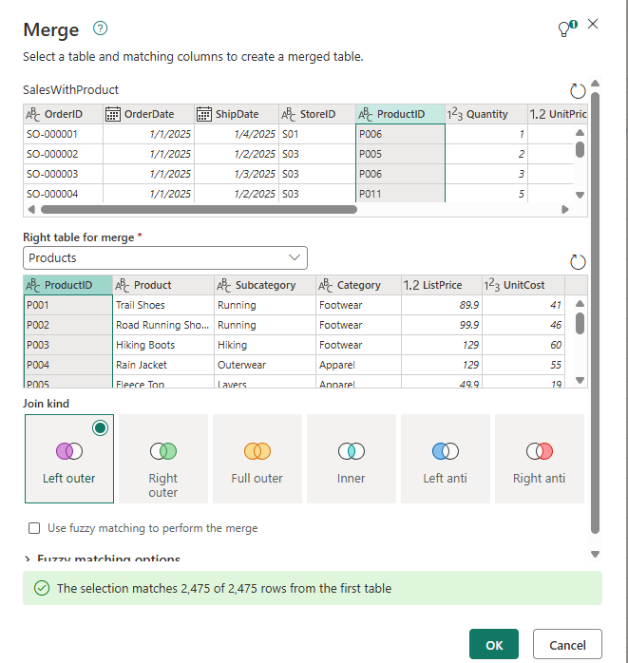
Merge Queries is a join on one or more matching columns. Choose the join kind:
| Join kind | Rows returned |
|---|---|
| Left Outer | All rows from the first table, matching rows from the second |
| Right Outer | All rows from the second table, matching from the first |
| Full Outer | All rows from both |
| Inner | Only matching rows |
| Left Anti | Rows in the first table with no match in the second |
| Right Anti | Rows in the second with no match in the first |
Notes:
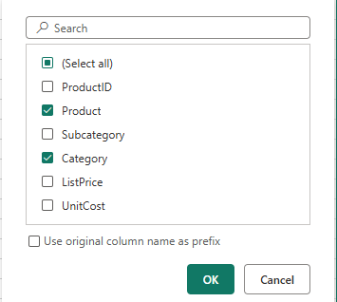
- The merge result adds a column of nested tables; expand it to choose which columns to bring in.
- Select columns in the same order in both tables for multi-column merges.
- Use compatible types and normalize business keys on both sides. Test case and whitespace variants on your connector. A fuzzy merge option exists for approximate text matching with a similarity threshold.
- A Left Anti merge is the classic way to find unmatched rows, such as orders with no matching customer (an integrity check) or products that never sold.
Worked example 2: enriching sales and finding orphans.
Scenario. Sales has ProductID and Amount; Products has ProductID, Name and Category. The business wants a sales table with Category, and a list of sales whose product is missing from the product list.
Reasoning.
- Verify
Products[ProductID]is unique, then use Left Outer withSalesfirst. A duplicate lookup key can multiply fact rows when matches are expanded. - Expand the new column, selecting only
Category. - Check column quality for
Category. An empty category may mean an unmatched product or a matched product with a missing category. Use the anti join to distinguish them. - For a dedicated orphan list, merge
SaleswithProductsusing Left Anti; the result contains only the unmatched sales.
Why alternatives fail. Inner would silently drop sales for unknown products and understate revenue. Append adds rows, not columns. A DAX lookup needs a suitable lookup key and would perform the enrichment in the model. A merge lets you inspect the matches before loading.
If both sources are in the same database, a merge can fold into a SQL join; a cross-source merge can require mashup-engine work or buffering. Check connector support, privacy settings, and actual folding behavior.
9. Keys for relationships
Relationships in Power BI link a column in one table to a column in another. Good keys are:
- Unique and non-null on the one side (a dimension). Duplicates prevent that column from being the one side. Confirm the grain and fix the key before choosing cardinality.
- Same type and format on both sides.
- Simple: a single column. Power BI relationships use one column on each side, so use a collision-safe encoding or an explicit mapping for a composite business key. Independently generated indexes do not establish a shared key.
- Stable: business keys that never change are better than names.
Use a stable mapping for surrogate keys, particularly when older fact partitions are not reloaded. To retain an unmatched fact, map it to the actual key of an explicit Unknown dimension member.
10. Configuring query load
After transformation, each query decides what reaches the model.
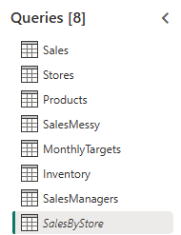
- Enable load (right-click a query). When unchecked, the query exists only in the Power Query layer and is italic in the Queries pane. Staging queries and parameter-like helper queries should not load.
- Include in report refresh controls whether the query is refreshed with the semantic model refresh in Desktop and the service. Exclude a query only if the model can tolerate stale data. A referenced query can still be evaluated as an input to another query.
- Close & Apply loads the results to the model; the Apply Changes banner appears when queries changed but are not yet loaded.
- In Desktop, enabled tables enter the semantic model. Import stores data; DirectQuery keeps the table definition and queries the source. Dataflows offer a separate way to stage reusable data.
- Query folding: when a step can be translated into the source's language (SQL), it runs at the source. View Native Query shows source queries for supported connectors and steps. A disabled menu alone does not prove that nothing folds. Check folding indicators or the query plan where available. Filter and project early when the result is equivalent.
Example. The staging query Orders_Raw reads a 120-million-row SQL table. The analyst filters to the last three years and removes 15 unused columns before any non-foldable step. The folded filter makes the source return 18 million rows instead of 120 million. Orders_Raw has load disabled; FactOrders, DimCustomer and DimProduct reference it.
11. Pitfalls and exam tips
- Use Unpivot Other Columns for new value columns when identifiers stay fixed, then check the new attribute names.
- A relationship needs matching types; fix types in Power Query rather than in DAX.
- Keys with leading zeros must stay Text.
- Inner joins can hide data; use Left Outer for enrichment and Left Anti for diagnostics.
- Choose reference when queries should share upstream changes, duplicate when they should diverge.
- Disable load for staging queries to save memory and keep the model tidy.
- Filter rows and remove columns as early as possible and before non-folding steps.
- Do not group away detail that reports still need.
- Exam tip: when options include a DAX calculated column and a Power Query step for the same row-level result, prefer a source or Power Query step when the logic depends only on source rows. Use a measure when the result must respond to filter context.
- Exam tip: when the stem says "reduce model size", think: remove columns and rows, change types, group to a coarser grain, disable load for helpers, replace high-cardinality text with keys.
12. Mini case study: orders and quarterly budgets
Case. A retailer imports order lines with OrderDate (text in yyyyMMdd format), CustomerID, CountryCode, ProductCode (text with leading zeros), CategoryCode, Qty, and UnitPrice. Its budget workbook has one row per country, category, and fiscal year, with Q1 through Q4 and an occasional Q4 Adjustment column. Reports compare actual and budget by country, category, and fiscal quarter.
Solution.
- Create
Orders_Rawwith load disabled. Promote headers and parse dates withDate.FromText([OrderDate], [Format = "yyyyMMdd", Culture = "en-US"]). Keep identifiers as text where their characters matter. Check parsing errors and use numeric types that suit quantity and price. - Build
FactSalesat order-line grain. ComputeLineAmountand use validated country, category, and fiscal quarter keys. Build dimensions from governed lists or validated reference queries; reject or map unknown values under agreed rules. - In the budget query, select the country, category, and fiscal year identifiers, then use Unpivot Other Columns. Map
Q1throughQ4to a fiscal quarter key. Use finance’s approved rule forQ4 Adjustment, or reconcile it separately. Do not interpret an adjustment as a fifth quarter. - Keep
FactBudgetat country–category–quarter grain. Link both facts to shared dimensions at those comparison grains. A shared quarter key must include the year. Keep day-level analysis for sales separate from budget comparison unless the business defines an allocation. - Load the facts and the dimensions, keeping staging queries out of the model. Check actual and budget totals independently before putting them on the same visual.
Joining the budget amount directly to order lines would repeat it for each matching line. Sharing dimensions preserves each fact’s grain.
Key terms
- Fixed Decimal Number: exact currency-style type with four decimals.
- Group By: aggregates rows by one or more columns.
- Unpivot / Pivot / Transpose: reshape operations between wide and tall layouts.
- Record / List: structured values in semi-structured data; expand them to columns or rows.
- Fact / dimension table: events with measures versus descriptive lookup entities.
- Reference / duplicate: a query that builds on another's output versus an independent copy.
- Merge / append: join columns versus stack rows.
- Left Anti: join returning first-table rows with no match.
- Surrogate key: artificial unique identifier such as an index.
- Query folding: translation of steps into source queries.
- Enable load: option controlling whether a query reaches the model.
Summary checklist
- I can pick the right data type (text for codes, fixed decimal for money, date for dates).
- I can create columns in Power Query and decide when DAX is more appropriate.
- I can group, pivot, unpivot (including other columns) and transpose.
- I can expand records and lists, choosing new rows versus extract values.
- I can split a flat table into fact and dimension tables with unique keys.
- I can choose reference or duplicate, merge join kinds, and append.
- I can disable load for staging queries and keep foldable steps first.
Official sources
-
Study guide for Exam PL-300: https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/pl-300 (opens in a new tab)
-
Power Query documentation: https://learn.microsoft.com/en-us/power-query/ (opens in a new tab)
-
Merge queries overview: https://learn.microsoft.com/en-us/power-query/merge-queries-overview (opens in a new tab)
-
Append queries: https://learn.microsoft.com/en-us/power-query/append-queries (opens in a new tab)
-
Pivot columns / unpivot columns: https://learn.microsoft.com/en-us/power-query/unpivot-column (opens in a new tab)
-
Query folding: https://learn.microsoft.com/en-us/power-query/query-folding-basics (opens in a new tab)
-
Star schema guidance: https://learn.microsoft.com/en-us/power-bi/guidance/star-schema (opens in a new tab)
-
Microsoft Learn, data types and Group By: https://learn.microsoft.com/en-us/power-query/data-types (opens in a new tab) and https://learn.microsoft.com/en-us/power-query/group-by (opens in a new tab)
-
Microsoft Learn, referencing queries: https://learn.microsoft.com/en-us/power-bi/guidance/power-query-referenced-queries (opens in a new tab)
-
Microsoft Learn, query load and refresh: https://learn.microsoft.com/en-us/power-bi/connect-data/refresh-include-in-report-refresh (opens in a new tab)
-
Microsoft Learn, Date.FromText: https://learn.microsoft.com/en-us/powerquery-m/date-fromtext (opens in a new tab)